● Open to Collaboration

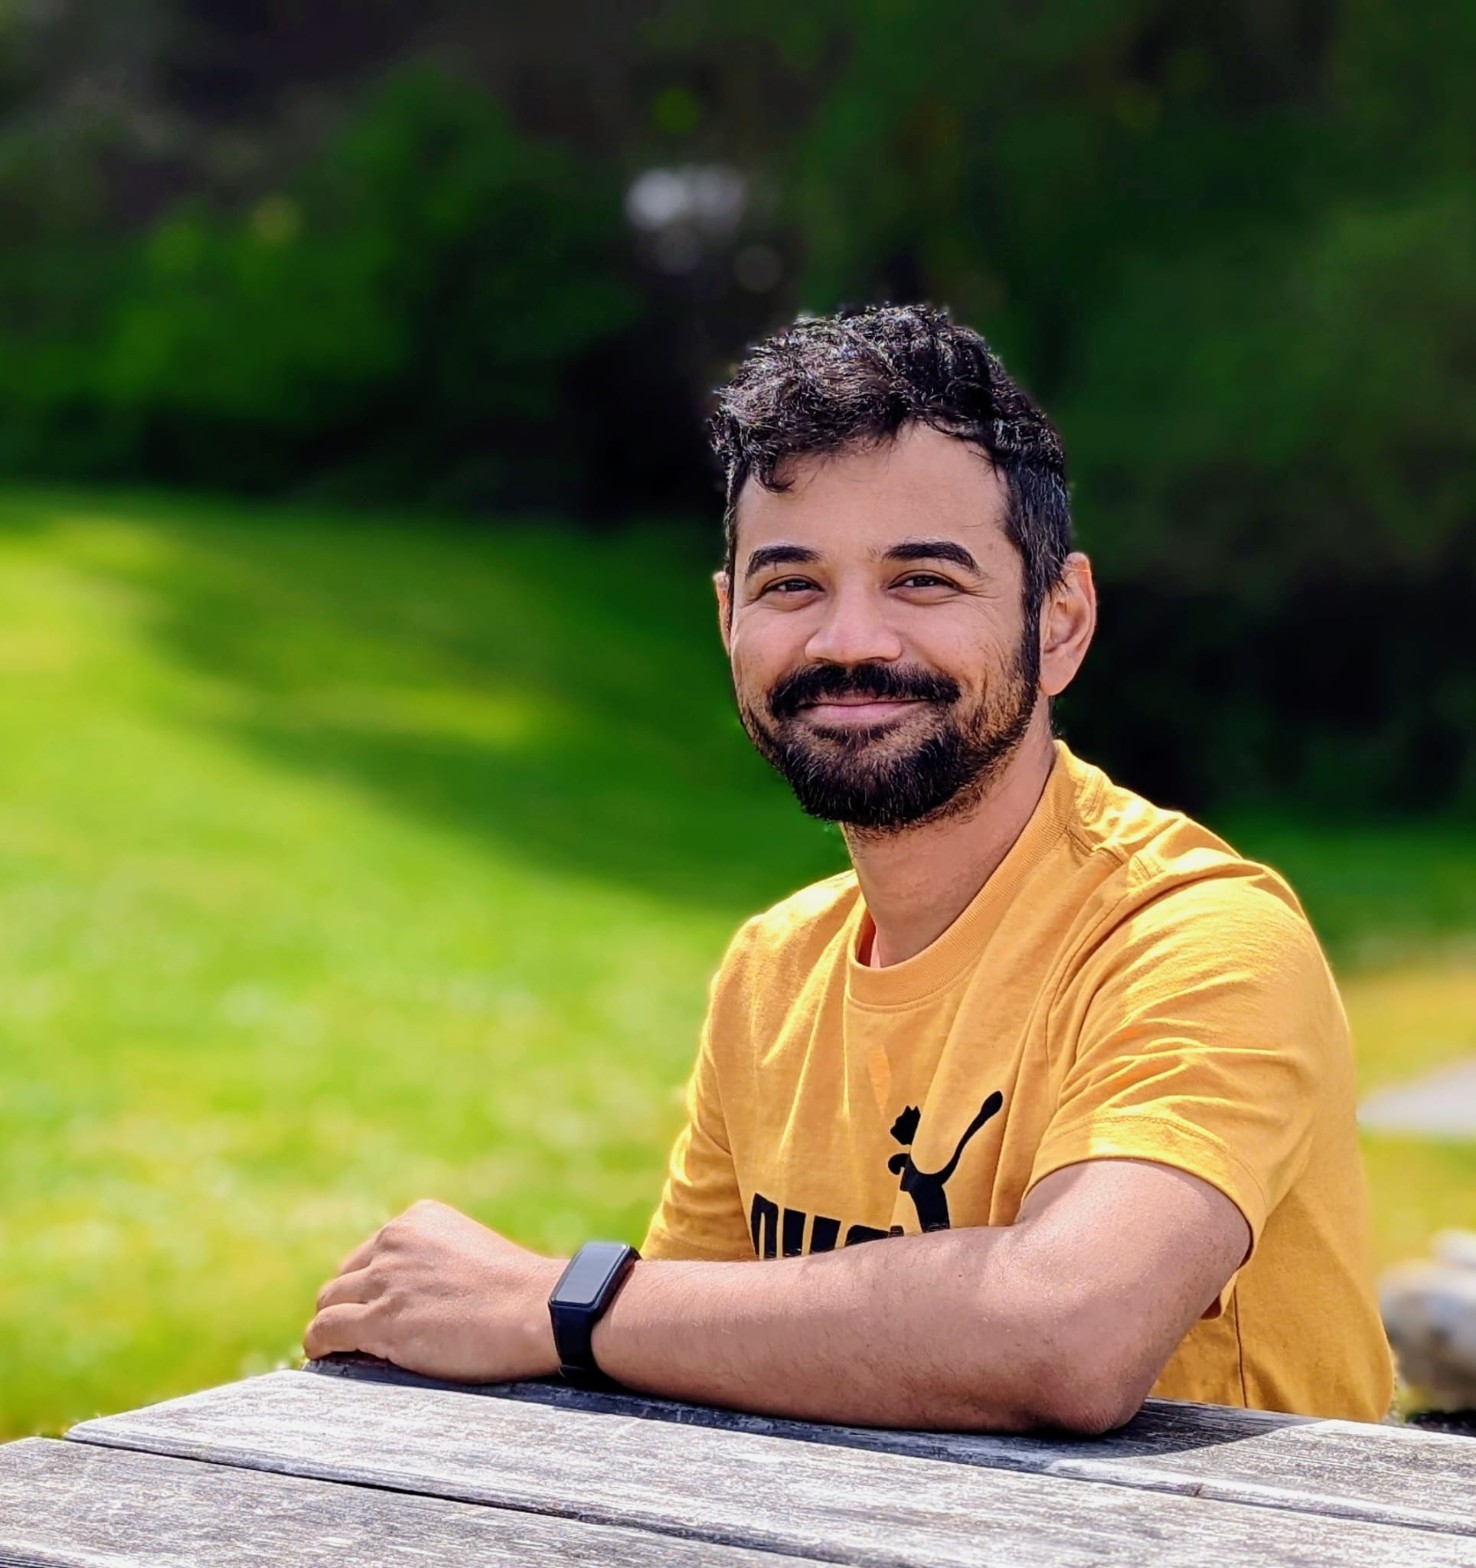
Mandip Goswami

Principal Scientist — Acoustics, Audio AI & NVH @ Amazon FT & Robotics

I lead acoustics development across one of the largest physical environments on Earth — Amazon's global network of fulfillment centers and robotics — and build the open datasets, benchmarks, and robust speech systems that are advancing room-acoustics research worldwide.

Mandip Goswami
…
Total HF Downloads · all-time
● live
7
Open Datasets
● live
5
Papers / Preprints
—
Community Likes
● live

Fetching live data from Hugging Face…

About

Acoustics meets audio machine learning

I sit at the intersection of industrial acoustics and audio machine learning — a combination that is rare and increasingly consequential as robotic environments, autonomous vehicles, and AI-native products all demand acoustic intelligence. At Amazon Fulfillment Technologies & Robotics, I lead acoustic safety infrastructure for one of the world's largest and most complex built environments — hundreds of fulfillment centers, thousands of robots, millions of square feet of noise. My work spans psychoacoustic modeling, NVH prediction at scale, room acoustics simulation, and applied deep learning for multi-source audio classification. I also contribute to the open research ecosystem through publicly available datasets, models, and benchmarks on Hugging Face — focused on room acoustics, machine listening, and spatial audio, and used by researchers across speech, audio ML, and acoustic simulation. My broader goal is to help build the next generation of AI systems that understand physical sound environments: robotics, AR/VR spatial audio, smart infrastructure, industrial monitoring, and acoustic digital twins.

Room AcousticsRoom Impulse Response (RIR) modelingReverberant Speech & DereverberationRobust Automatic Speech RecognitionAcoustic Parameter Estimation (RT60, DRR, C50/C80)Audio Anomaly Detection & Predictive MaintenanceReproducible ML & Open Datasets
Impact & Adoption

Research used by the community, at scale

Open datasets with real-world reach. Every corpus ships with validation tooling, checksums, and reference baselines — and the community has adopted them at scale.

…
Lifetime Downloads
Aggregated live from the Hugging Face API on every page load.
7
Open Datasets & Models
Spanning simulated RIRs, reverberant speech, industrial machine sound, and UI earcons.
5
Interactive Tools
Browser-based demos for acoustic analysis, benchmarking, and anomaly detection.
5
Preprints on arXiv
Each paired with an open dataset, benchmark, or tool for full reproducibility.
Publications

Papers & Preprints

Peer-oriented research on room acoustics, reverberant speech, and robust ASR — each paper paired with an open dataset, benchmark, or tool for full reproducibility.

RIR-Mega: A Large-Scale Simulated Room Impulse Response Dataset for Machine Learning and Room Acoustics Modeling

arXiv (eess.AS, eess.SP)Oct 2025

A large collection of simulated RIRs with a compact, machine-friendly metadata schema, a Hugging Face Datasets loader, validation and checksum tooling, and a reference RT60-regression baseline. A Random Forest on lightweight time/spectral features reaches ~0.013 s MAE / ~0.022 s RMSE on a 36k/4k split. A streaming subset (1,000 linear + 3,000 circular array RIRs) is on Hugging Face; the full 50,000-RIR archive is on Zenodo.

✓ Dataset✓ Benchmark✓ Code
RIRDatasetRoom AcousticsRT60Reproducibility

RIR-Mega-Speech: A Reverberant Speech Corpus with Comprehensive Acoustic Metadata and Reproducible Evaluation

arXivJan 2026

A large-scale reverberant speech corpus built by convolving LibriSpeech utterances with simulated RIRs from the RIR-Mega collection. Each reverberant utterance carries per-file acoustic metadata, enabling controlled analysis of reverberation effects on speech-processing systems with transparent, reproducible metrics.

✓ Dataset✓ Benchmark✓ Code
Reverberant SpeechASRCorpusReproducibility

Whisper-RIR-Mega: A Paired Clean-Reverberant Speech Benchmark for ASR Robustness to Room Acoustics

arXivFeb 2026

A benchmark of paired clean and reverberant speech for evaluating ASR robustness to room acoustics. Each sample pairs clean LibriSpeech audio with the same utterance convolved with a RIR-Mega impulse response, together with ground-truth transcripts and RIR metadata (RT60, DRR, C50). Accompanies a fine-tuned Whisper-Medium model specialized for reverberant speech.

✓ Dataset✓ Benchmark✓ Model✓ Code
BenchmarkWhisperASR RobustnessRoom Acoustics

Acoustivision Pro: An Open-Source Interactive Platform for Room Impulse Response Analysis and Acoustic Characterization

arXivFeb 2026

An open-source, interactive platform for visualizing and analyzing room impulse responses and characterizing acoustic spaces — bringing RT60, DRR, clarity (C50/C80), definition (D50), and early-decay-time analysis into an accessible, reproducible tool for the acoustics community.

✓ Code
ToolVisualizationAcoustic CharacterizationOpen Source

BeepBank-500: A Compact Synthetic Earcon / Alert Mini-Dataset for UI Sound Research

arXivSep 2025

A fully synthetic earcon/alert mini-dataset of short tones and triads generated from a controlled parameter grid (waveform family, f0, duration, envelope, amplitude modulation, Schroeder-style reverbs). Ships with a metadata schema and lightweight baselines, released CC0 for UI-sound research.

✓ Dataset✓ Code
EarconsUI SoundSyntheticDataset
Open Data

Datasets

Download counts, likes, and update dates below are pulled live from the Hugging Face API every time this page loads.

Loading datasets…

Models

Models

Fine-tuned models for robust speech recognition under real room acoustics.

Loading models…

Visual Results

What the acoustics look like

Real figures from the published papers — room-acoustics statistics, reverberant-speech spectrograms, and dataset coverage plots. Each is linked to its source preprint.

RIR-Mega — Validation Summary

RIR-Mega — Validation Summary

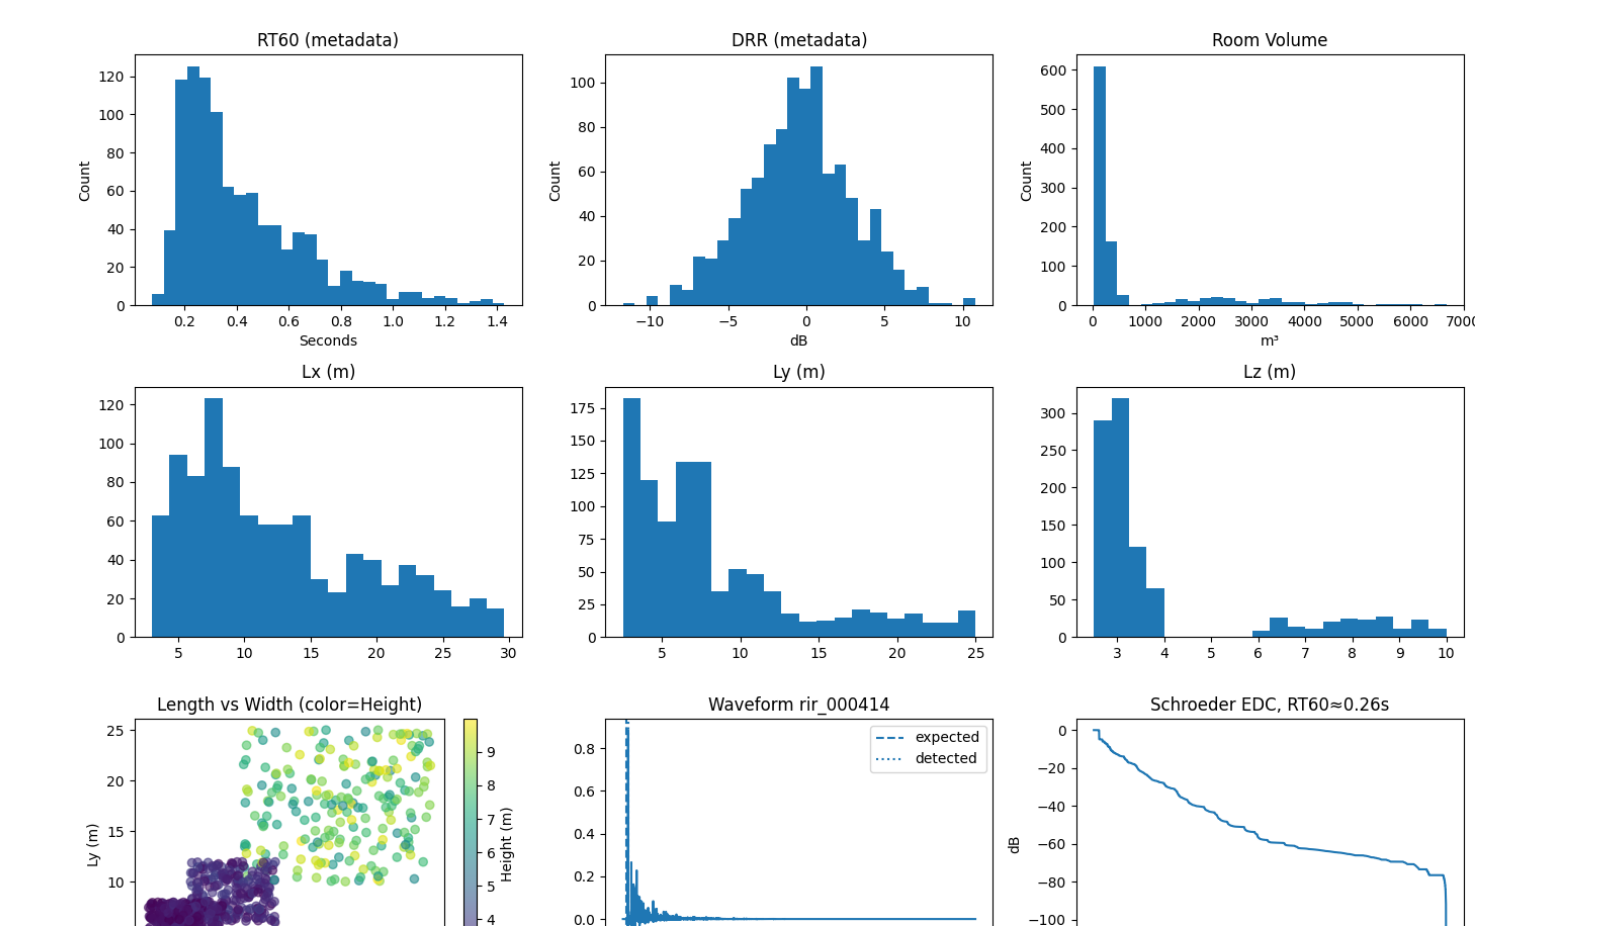
Dataset validation across 50,000 simulated RIRs: RT60, DRR, and room-volume distributions, room-dimension histograms, and a Schroeder energy-decay curve (RT60 ≈ 0.26 s).
arXiv:2510.18917, Fig. 2
Clean vs. Reverberant Speech

Clean vs. Reverberant Speech

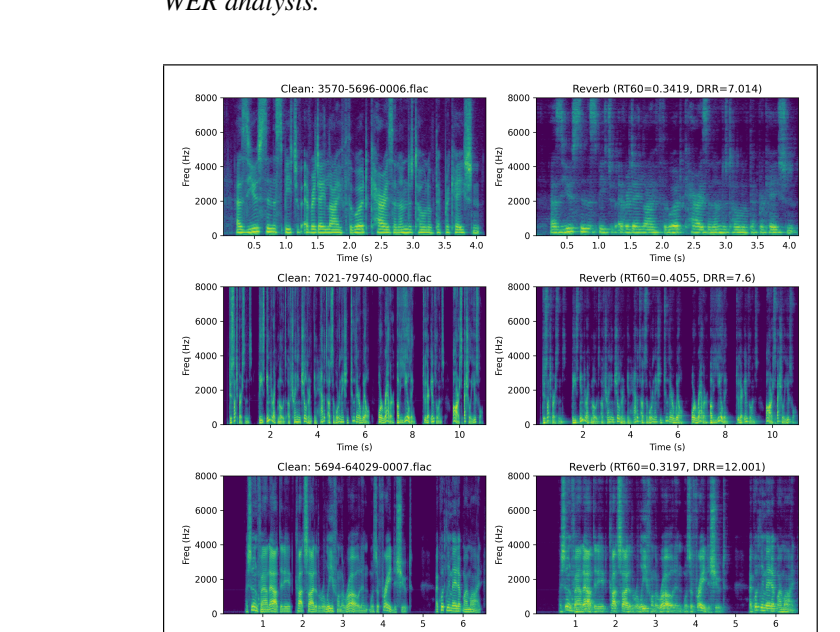
Spectrogram comparison of three utterances — clean (left) vs. the same speech convolved with a room impulse response (right). The smearing of formant structure under reverberation is clearly visible.
arXiv:2601.19949, Fig. 5
Duration vs. RT60 Coverage

Duration vs. RT60 Coverage

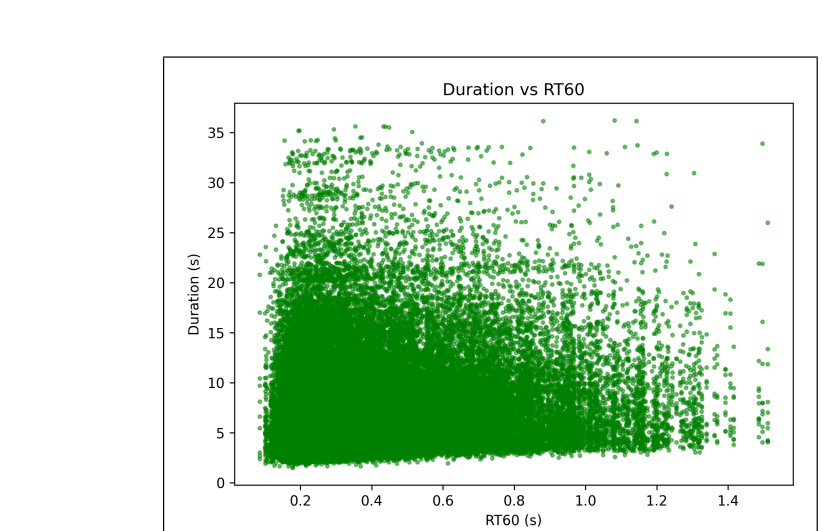
Utterance duration against RT60 across the reverberant corpus — long and short utterances span all RT60 bins, reducing confounding in word-error-rate analysis.
arXiv:2601.19949, Fig. 4
BeepBank-500 — Log-Mel Spectrograms

BeepBank-500 — Log-Mel Spectrograms

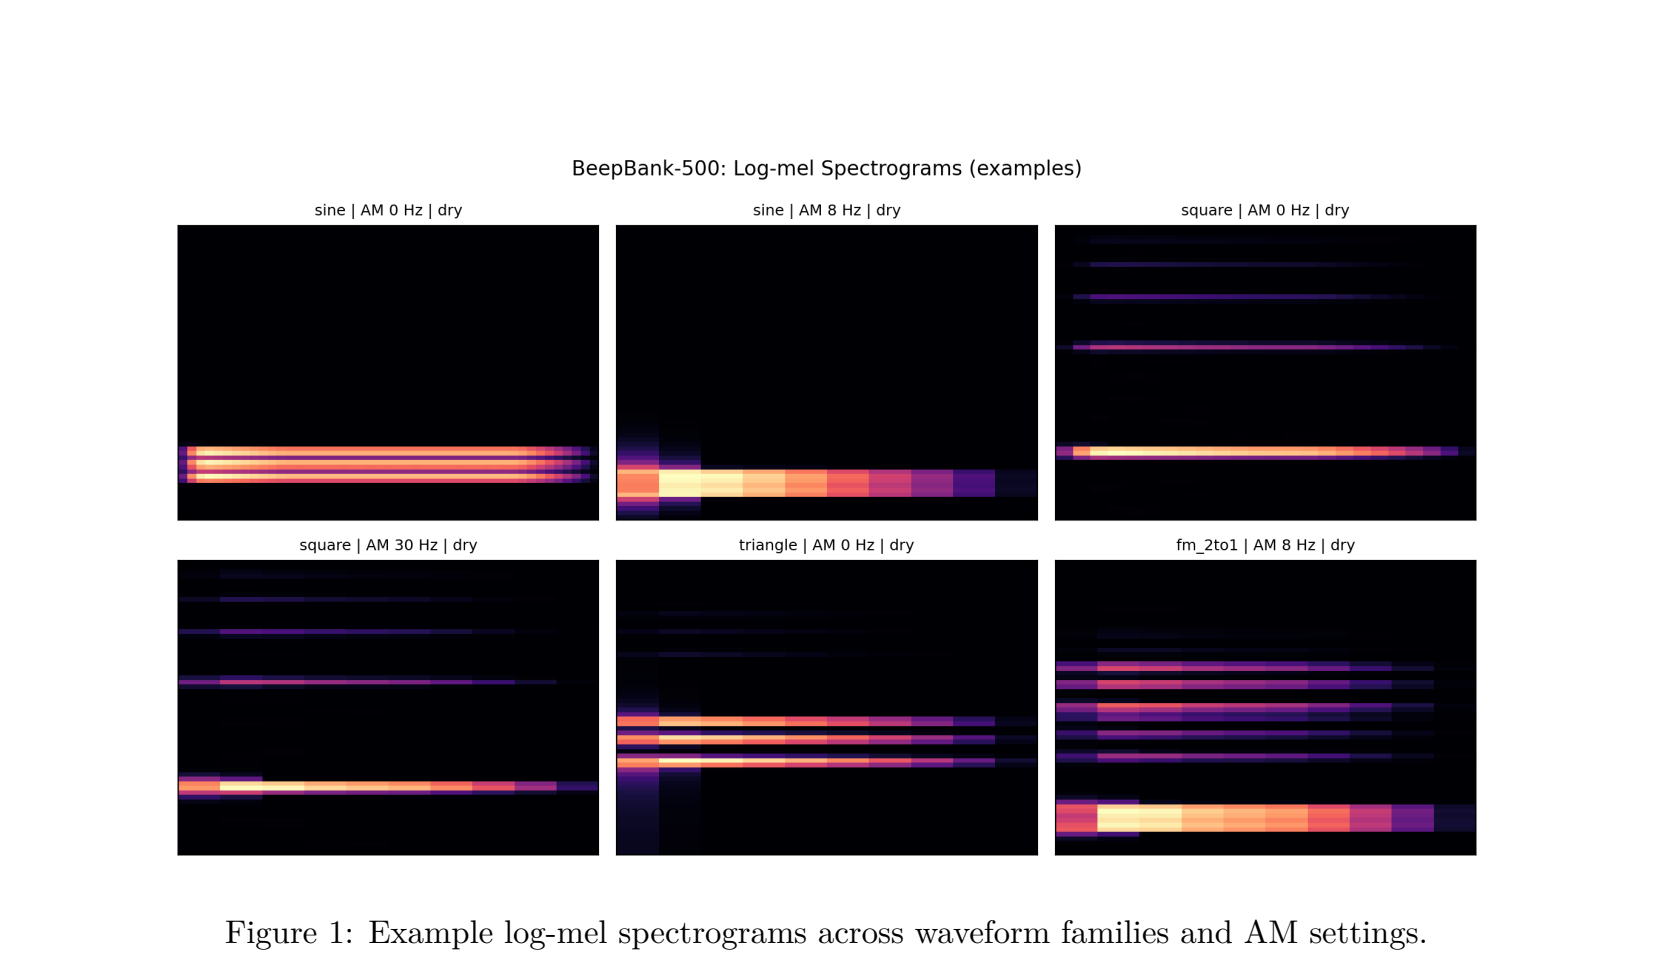
Example log-mel spectrograms across synthetic waveform families (sine, square, triangle, FM) and amplitude-modulation settings — the controlled parameter grid behind the earcon dataset.
arXiv:2509.17277, Fig. 1
Interactive

Demos & Spaces

Live, interactive tools and leaderboards you can try in the browser.

Career

Experience

A decade spanning automotive NVH, aeroacoustics, and large-scale industrial acoustics & audio AI.

Principal Scientist, Acoustics & Applied AI
Amazon — Fulfillment Technologies & Robotics
Apr 2025 – Present · Bellevue, WA
  • Lead acoustic safety infrastructure for one of the world's largest built environments — hundreds of fulfillment centers and thousands of robots.
  • Build large-scale acoustic simulation frameworks for warehouse environments.
  • Deliver noise mitigation and acoustic optimization for conveyor and robotic systems.
  • Develop ML models for industrial sound classification and diagnostics (MFCC, spectral features, DNNs).
  • Create psychoacoustic models for worker-centric acoustic design and internal sound-mapping tools.
Senior Scientist, Acoustics & NVH
Amazon
Aug 2022 – Apr 2025 · Seattle, WA
  • Developed proprietary sound-mapping software fusing acoustic measurement with 3D spatial analysis across fulfillment-center deployments.
  • Built predictive acoustic models for scalable noise forecasting of new facility designs, cutting design iteration and physical prototyping cost.
  • Applied audio-classification pipelines (MFCCs, CNNs, deep learning) for multi-source acoustic event detection in high-noise environments.
  • Engineered psychoacoustic noise-mitigation algorithms aligned with OSHA and auditory-health standards.
Senior Acoustics NVH Engineer
Amazon — Worldwide Design & Engineering
Oct 2021 – Aug 2022 · Seattle, WA
  • Early contributor to Amazon's acoustics function and first full-time acoustician in the WW Design & Engineering org.
  • Built core acoustic measurement and analysis infrastructure from the ground up.
Acoustics NVH Engineer
Amazon — Worldwide Design & Engineering
Nov 2019 – Oct 2021 · Greater Seattle Area
  • Established measurement, analysis, and acoustic design practices across worldwide facilities.
NVH Test Engineer — Vehicle Sciences
FCA Fiat Chrysler Automobiles
Jun 2016 – Nov 2019 · Auburn Hills, MI
  • Wind-noise testing via subjective road evaluation and objective wind-tunnel evaluation.
  • Developed vehicle prototypes for aeroacoustic evaluation and improved cabin speech intelligibility.
  • Improved acoustic packaging for sound absorption and transmission loss; collaborated with CFD/Aero on cabin aeroacoustics.
Design & Development Engineer — Vehicle Interior R&D
Maruti Suzuki India Limited
Aug 2012 – Jul 2015 · Gurgaon, India
  • Developed NVH barriers/absorbers, injection-molded plastic trims, and extrusion-molded rubber parts.
  • Studied performance, weight, and cost tradeoffs of NVH material composites.
Credentials

Education, Skills & Honors

🎓 Education

  • University of Cincinnati
    M.S., Mechanical Engineering — Structural Dynamics & Vibrations
  • Maulana Azad National Institute of Technology (MANIT)
    B.Tech., Mechanical Engineering

🏆 Honors & Awards

  • Gold Medalist — All India Inter-NIT Chess Championship
  • Rank Holder — State Board Merit List
  • University Grant Scholarship
  • Exceptional Performer, 2013–14

📜 Certifications

  • Generative AI with Large Language Models
  • Google Street View Trusted Professional Photographer

🧰 Technical Skills

PsychoacousticsRoom Acoustics (FEM / BEM / Ray Tracing)NVH SimulationAudio Deep Learning (CNNs, Transformers)Whisper Fine-TuningMFCC & Spectral FeaturesSound Event DetectionSpeaker DetectionSignal ProcessingPythonNext.jsHugging Face EcosystemDeep Neural NetworksAlgorithms

🌐 Languages

English (Full Professional)Hindi (Professional Working)Japanese (Limited Working)Assamese (Native / Bilingual)
Get in touch

Let's build acoustic intelligence together

I enjoy connecting with researchers, engineers, and builders working on acoustics, audio ML, spatial audio, or machine perception.